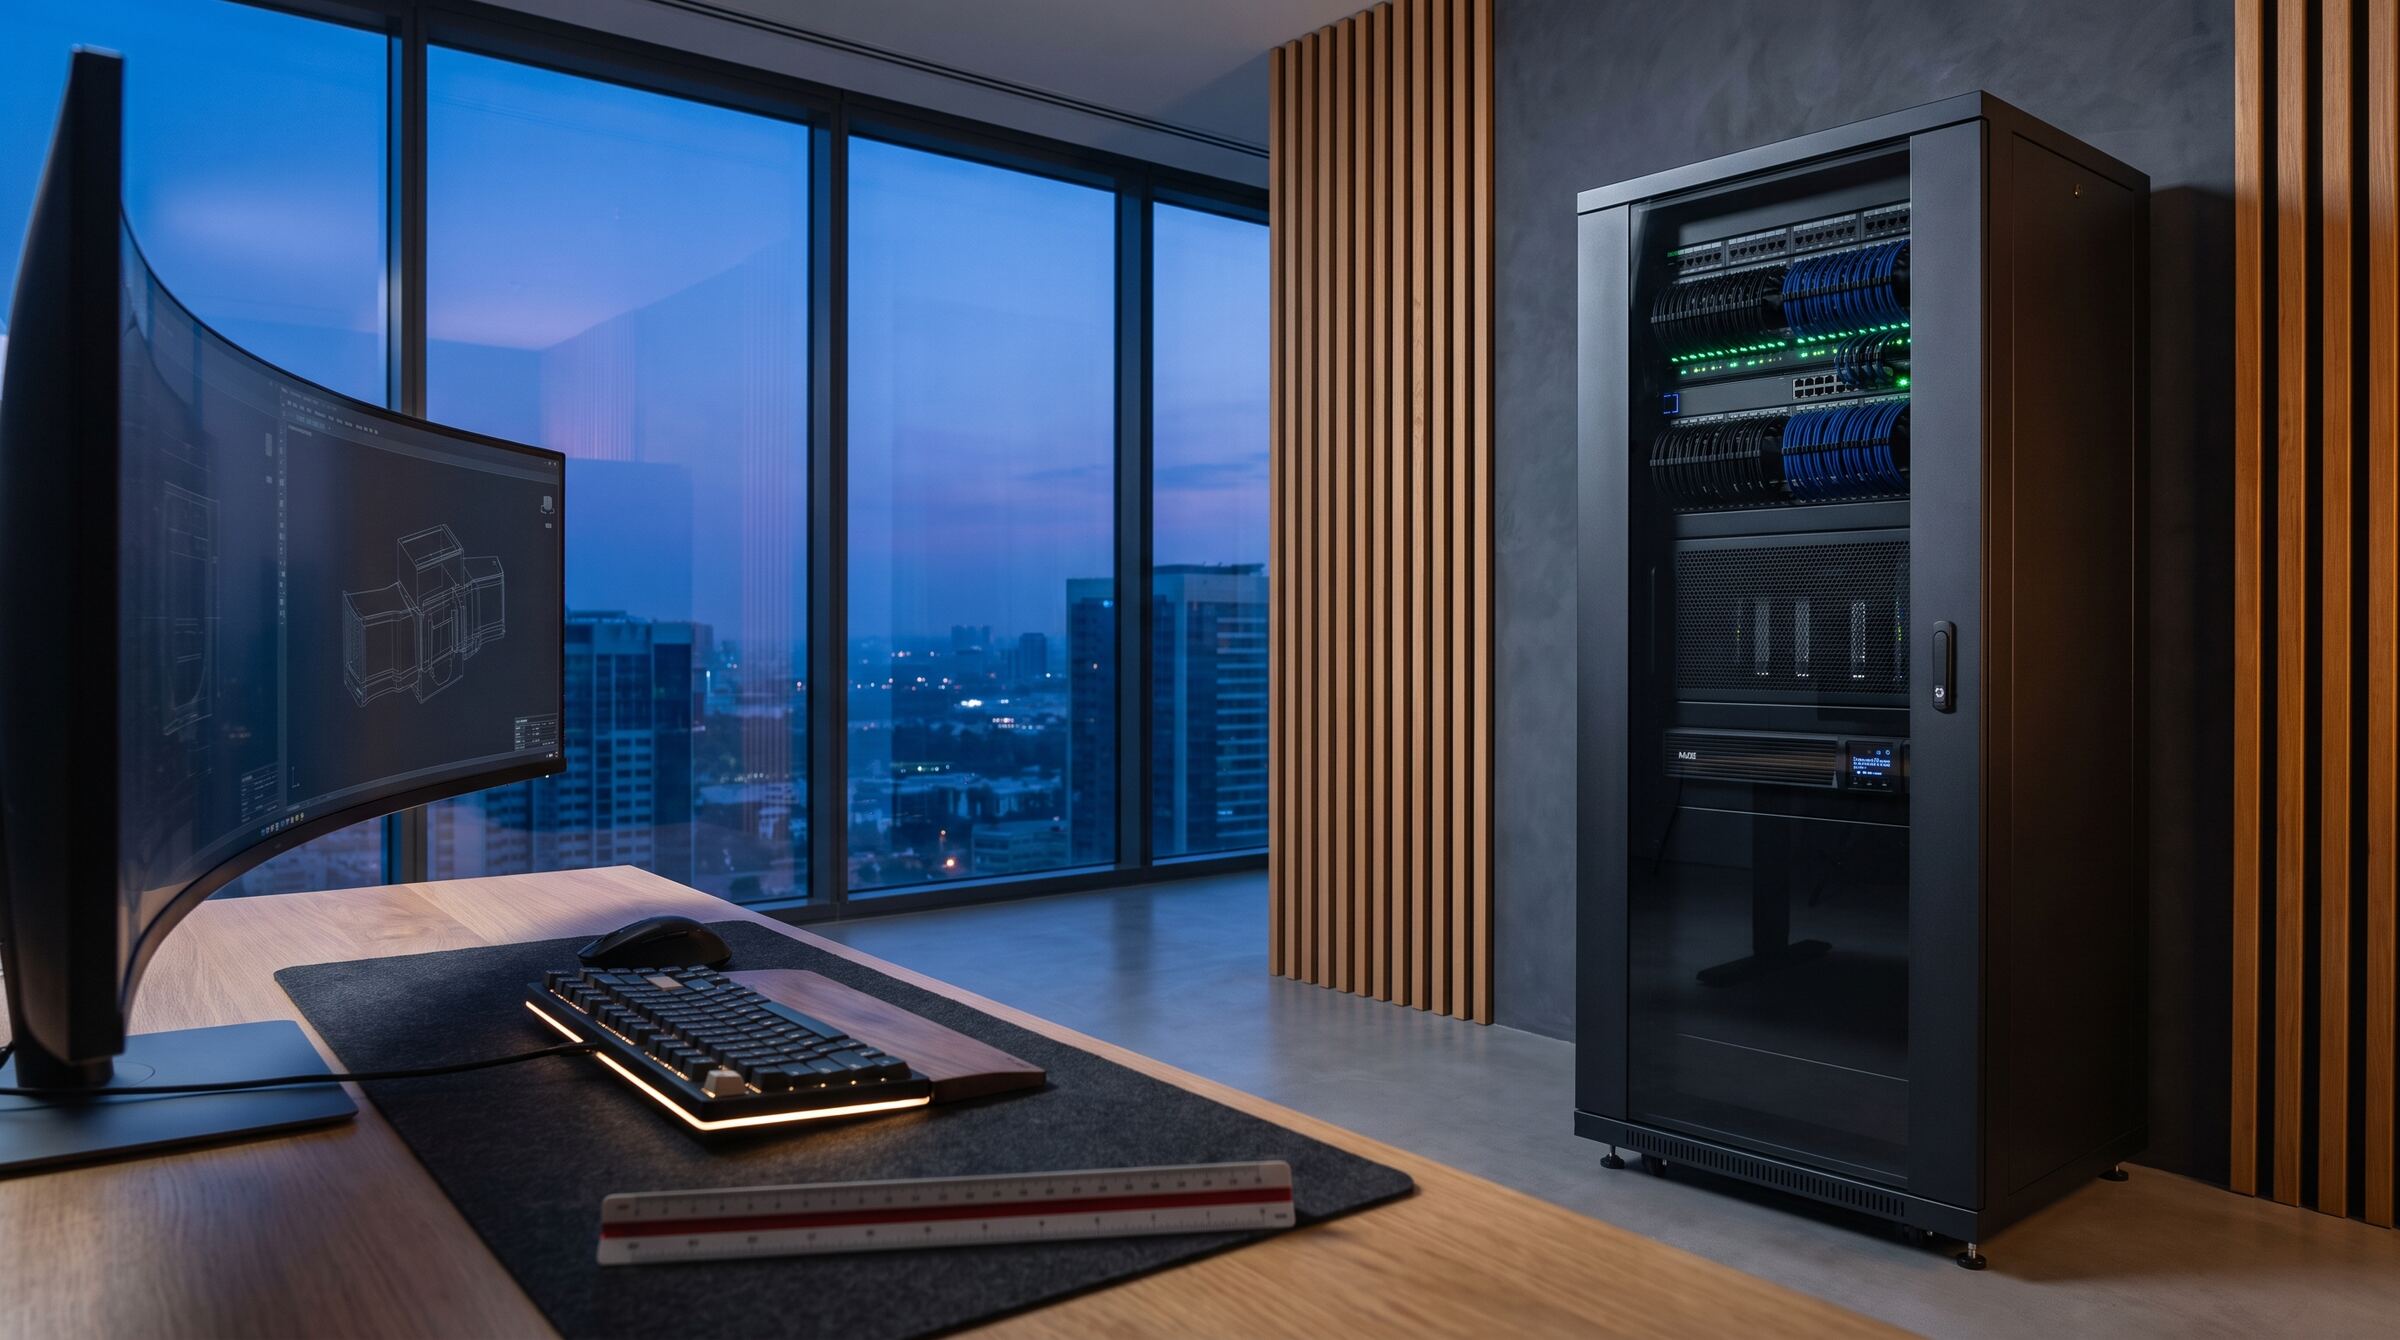
Open server rack next to a CAD workstation with a curved monitor, in a modern office overlooking the city skyline at dusk
← All solutions

IT architecture • High performance • On-premises AI & HPC

High-performance server infrastructure without a separate server room. Dedicated AI compute without cloud subscriptions.

We design and deploy infrastructure matched to your office space and your actual compute workload. From compact, quiet 15–18U rack cabinets that house a complete network and server stack, to scalable compute workstations and GPU-accelerated clusters (from single inference nodes and multi-GPU units to NVIDIA DGX-class systems) for local AI models and render farms. You get full control over your data, quiet operation in the office and no performance trade-offs.

See environment specifications →
From a 15U micro rackto a complete server room
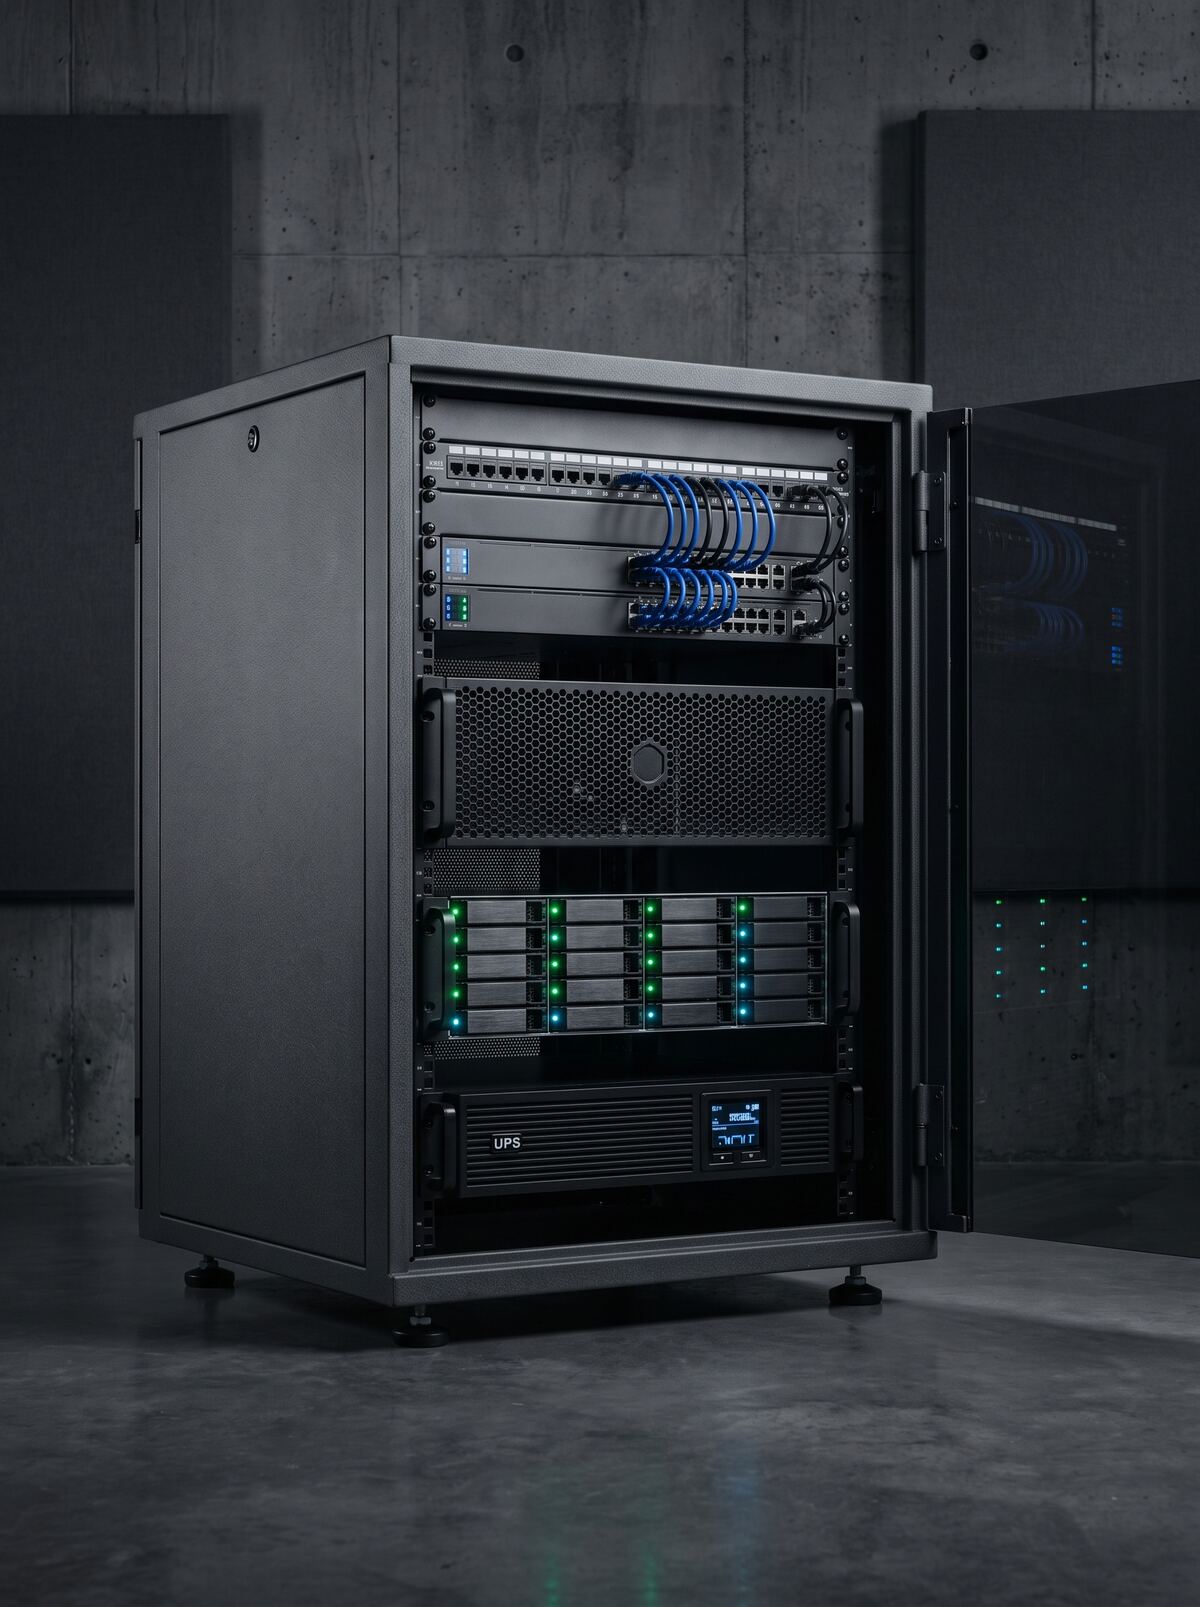
Open rack cabinet with patch panels, network switches, a disk array and a UPS

Engineering pragmatism vs. technology myths

Real engineering begins where the dogma of the “expensive server room” ends.

Most companies either assume that a stable IT environment requires a dedicated, air-conditioned room costing hundreds of thousands of PLN, or they dismiss the issue altogether, stuffing random desktop PCs under desks and into utility closets. Both paths are dead ends.

Everything a modern organization needs fits into a single, clean-looking 15–18U office rack cabinet. We design complete, integrated environments: a virtualization server, a storage array, a redundant router, a managed 10GbE switch, a hardware firewall and a UPS integrated with automatic machine shutdown. Everything in one place, with meticulously dressed cabling and no cable clutter.

A rack doesn’t have to howl like a fighter jet on takeoff. We build custom servers in 2U–4U industrial chassis where, instead of tiny, loud 1U turbine fans, we use airflow-optimized heatsinks and quiet, low-noise industrial fans. The server can sit right in an open-plan office or a hallway without disturbing your team.

Running a local AI assistant or a render farm doesn’t require an enterprise budget or overpaying for the cloud. We build the architecture in modules: starting with a single inference accelerator, moving through multi-GPU compute servers, up to dual DGX-class nodes. The hardware grows with the scale of your operations — always on-premises, with predictable costs and full control over your data.

Hardware architecture tiers

Three deployment scenarios. Precisely matched to your space and workloads.

There is no one-size-fits-all solution. We select the architecture based on heat load, your office’s acoustic profile and your team’s actual I/O and compute requirements.

Standard 01

Quiet office micro data center (15–18U rack)

Designed for: open-plan offices, design studios and law firms without a dedicated server room.

Architecture specification

A complete, integrated network and server stack enclosed in a single sound-dampened, desk-height office cabinet (approx. 90–100 cm).

Key components

  • Quiet 2U/4U unit with low-RPM industrial fans (< 40 dB(A)).
  • Hardware firewall with IDS/IPS and secure site-to-site VPN.
  • Managed 10GbE switch with passive or semi-passive cooling.
  • Centralized online UPS with a safe-shutdown module for all machines.

Result: quiet operation in the office, no need for a separate room and fully organized cabling.

Standard 02

High-availability clusters (Core & All-NVMe Storage)

Designed for: mid-sized and large organizations, multi-site companies and mission-critical SQL databases.

Architecture specification

Redundant high-availability (HA) server virtualization environment built on proven hypervisors (Proxmox VE / KVM), with N+1 redundant power.

Key components

  • Fast ZFS storage pools on enterprise U.2 / NVMe drives.
  • 25GbE / 100GbE backbone that eliminates latency bottlenecks in the cluster.
  • Automatic virtual machine failover if a physical node fails.
  • Independent backup path with automatic off-site snapshot rotation.

Result: operational continuity with no single point of failure and resilience against downtime.

Standard 03

Modular HPC, private AI & compute farms

Designed for: design and 3D/VFX studios, R&D departments and companies deploying local AI models.

Architecture specification

Scalable environments — from a single workstation to multi-machine clusters.

Key components

  • Multi-GPU systems for local LLM inference and CAD rendering; custom-built workstations and servers engineered around PCIe layout, power budget and cooling for 24/7 operation.
  • Enterprise & DGX nodes: integrated platforms that can be clustered for demanding simulations.
  • Compute sovereignty: all processing stays within your LAN — sensitive models and data are never sent to external services.

Result: scalability without cloud fees.

See AI use cases →

Design and 3D/VFX studios

No-compromise workstations — CAD, BIM and rendering without the wait.

Engineering design, BIM modeling and GPU rendering demand more power than office PCs can deliver. We build professional workstations for design studios, architecture firms and 3D/VFX studios.

  • Workstation-class platformCertified platforms with the fastest processors available for professional applications (up to 96 cores) and up to 2 TB of ECC RAM (RDIMM). Available in desktop or rack chassis — rack versions with front-panel ports.
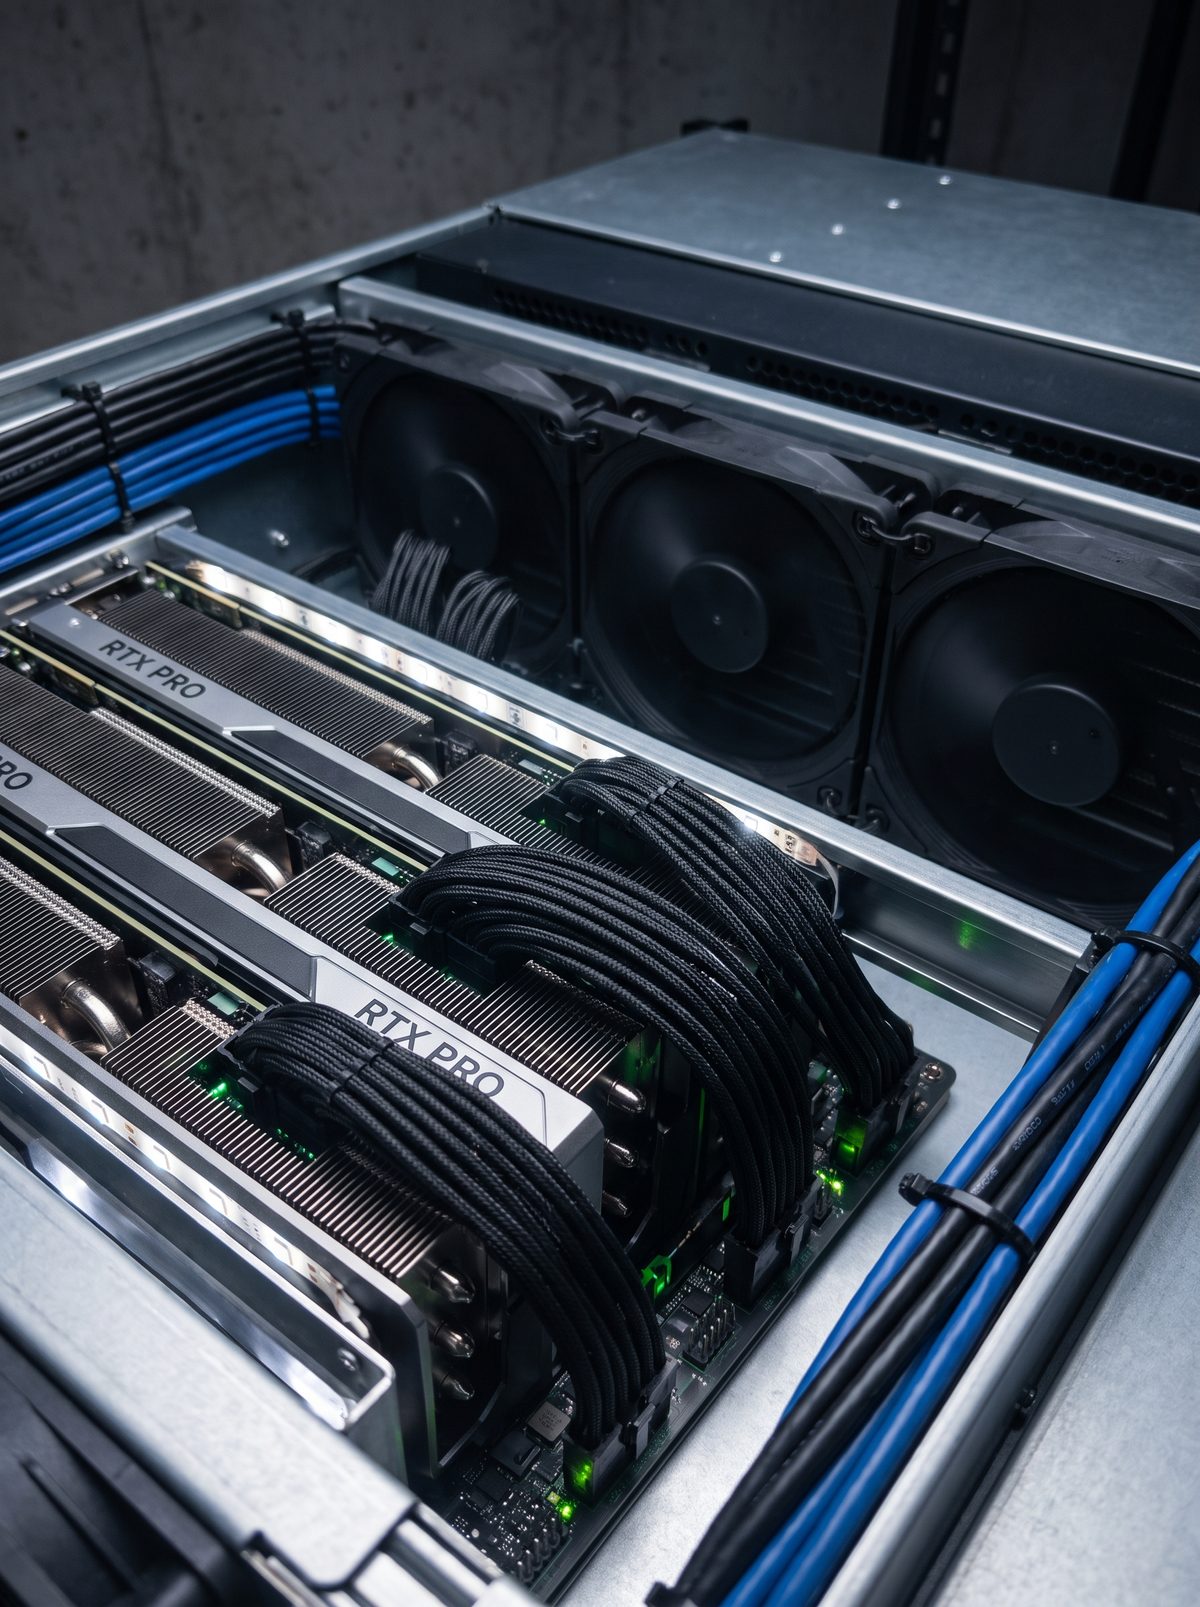
  • NVIDIA RTX PRO GPUsProfessional graphics cards from the RTX PRO family in single- and multi-GPU configurations — power for CAD, BIM and GPU rendering in one workstation.
  • NVMe PCIe Gen5 drives and arraysThe fastest drives available for working with large project files and rendered scenes, with no storage bottlenecks.
  • 10Gbit networking and remote accessA fast connection to your company infrastructure and secure remote access to the workstation — full performance outside the office, too.
Open server chassis with installed RTX PRO graphics cards and neatly routed cabling

Tested with professional software

  • AutoCAD
  • Revit
  • 3ds Max
  • V-Ray
  • Redshift
  • Blender

Optional extras

  • ECC memory (RDIMM)
  • Calibrated monitors
  • Multi-monitor setups
  • Quiet chassis (< 40 dB(A))

The same workstation can also serve as a local AI node — no extra hardware needed.

See AI use cases →
Operational resilience & redundancy

Infrastructure designed for the moment something goes wrong.

The true quality of an architecture is tested by a power failure, human error or a failed drive. In cluster configurations (Standard 02), we build environments on a firm principle: the failure of a single component does not bring the office to a halt — services are automatically restarted on a healthy node.

Architecture with no single point of failure (No SPOF)

Dual server power supplies connected to separate phases, switch port aggregation (LACP) and virtual machine clusters that automatically resume work on a healthy unit if a physical node fails.

Immutable snapshots and isolated copies

Strong protection against ransomware and accidental file deletion. ZFS systems automatically create immutable, read-only data snapshots that are replicated asynchronously to a secure, isolated location.

Power management and automated shutdown procedures

Online UPS units networked with the servers. During an extended power outage, the system doesn’t wait for the power to run out: it suspends non-essential tasks, safely flushes SQL databases to NVMe drives and shuts the machines down without risking data structure corruption.

Active 24/7 telemetry and early diagnostics

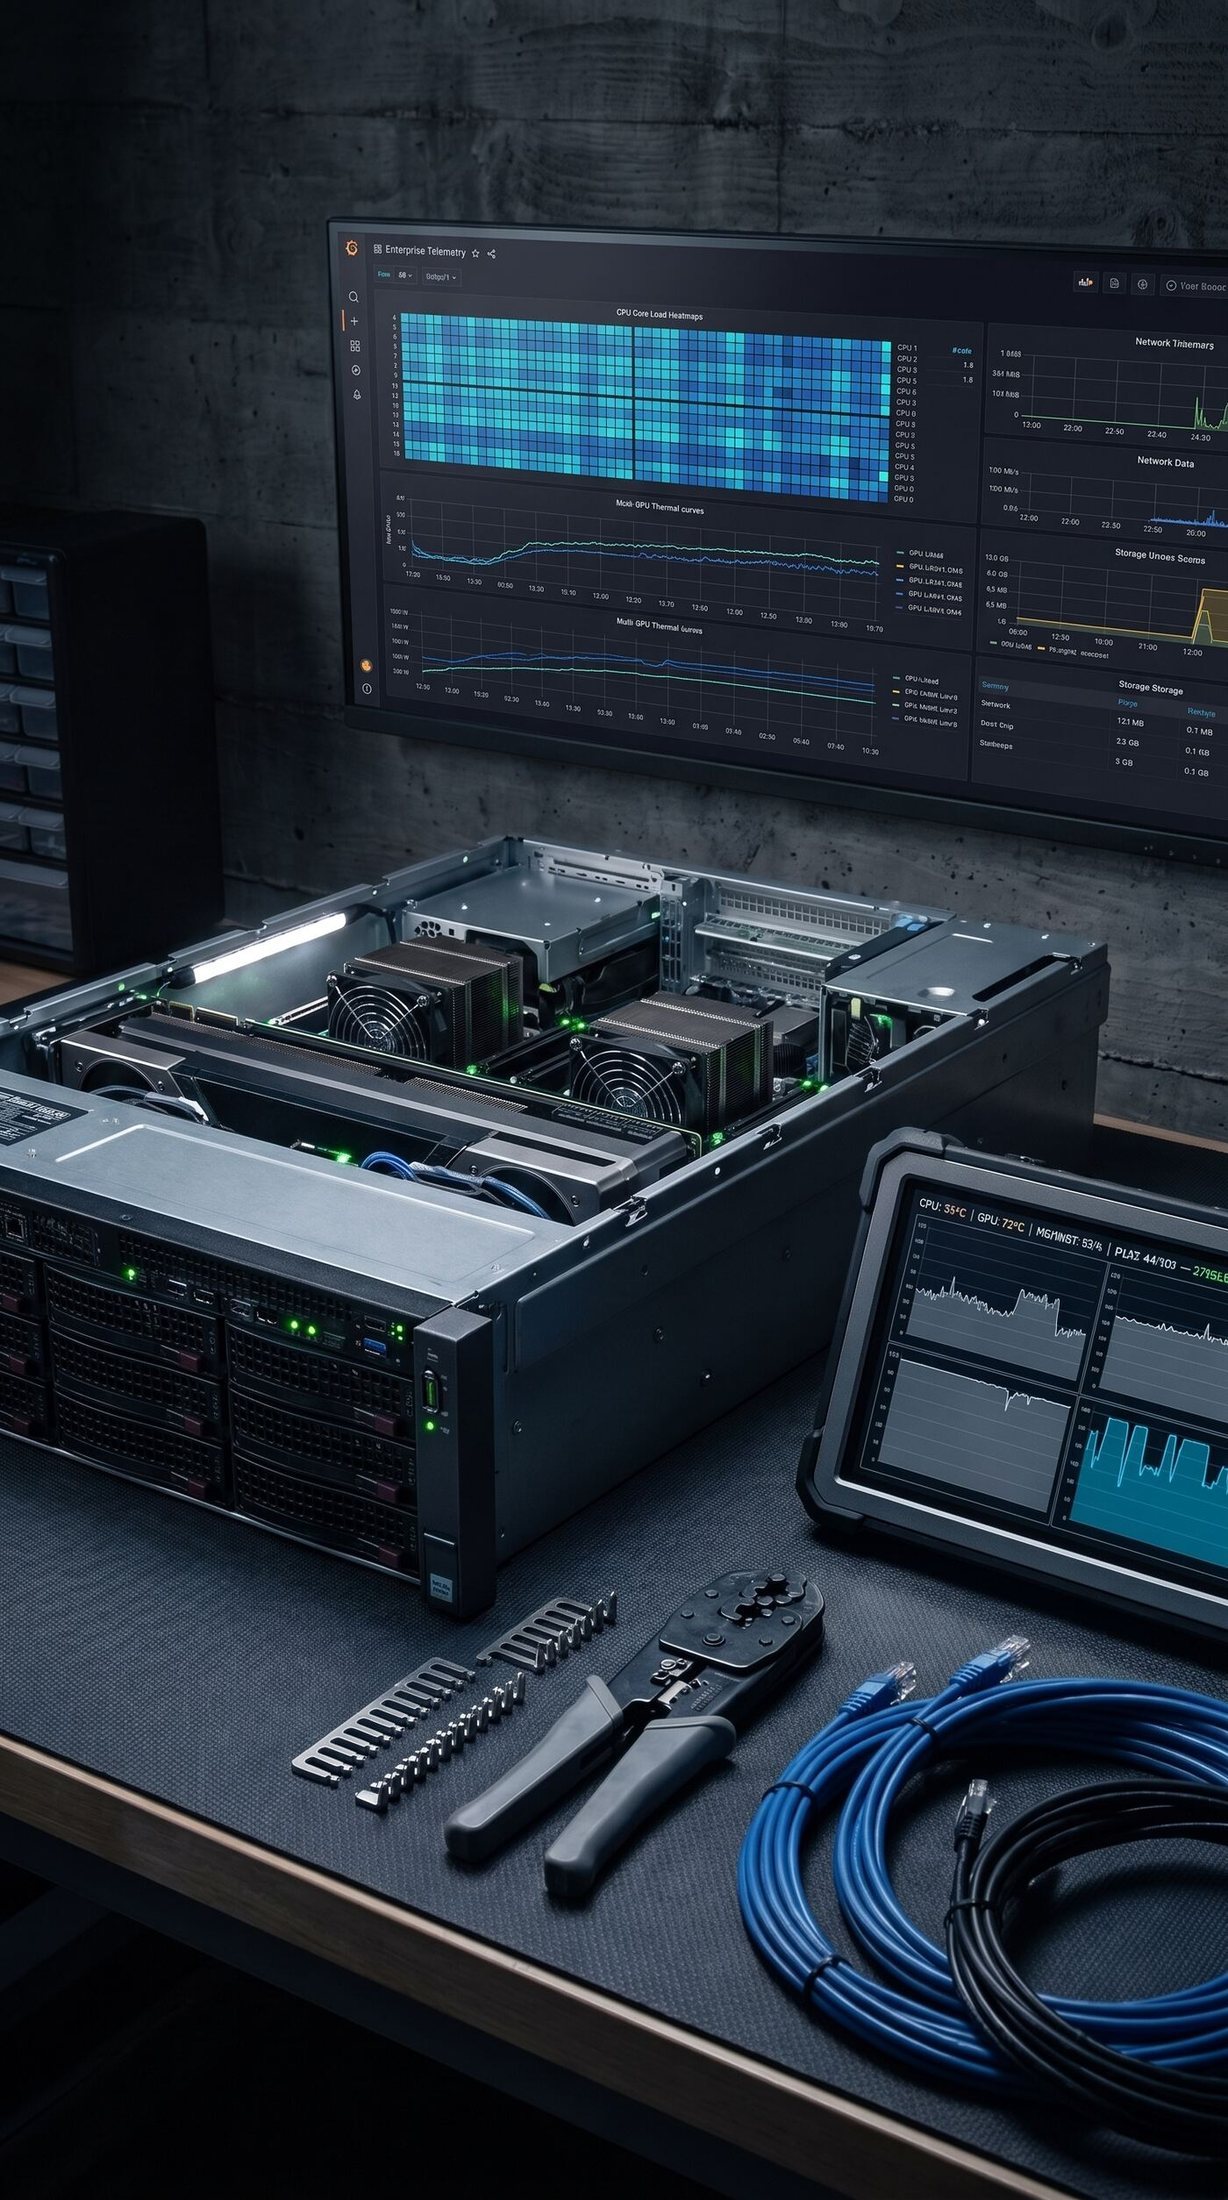
Environmental monitoring: temperature sensors in the rack, power rail voltages, fan speeds and drive S.M.A.R.T. data. We identify hardware degradation and replace components before a failure occurs.

Disassembled rack server with visible GPU heatsinks and fans, in front of a monitor showing CPU/GPU telemetry and a diagnostic tablet

PCS design methodology

We design the architecture around the way you work — we don’t sell off‑the‑shelf kits.

Every deployment is based on hard measurement data: we analyze the room’s heat load, the I/O read/write profile and your applications’ network requirements.

  1. 01
    Audit and environmental assessment

    We assess existing LAN load, application IOPS demand, available office space, and the thermal and acoustic conditions for the planned hardware.

  2. 02
    Architecture design and power budget

    We select the optimal topology: rack size (15–18U or a server room), airflow calculations, redundant power paths, and the configuration of compute and storage nodes.

  3. 03
    Lab assembly and 72-hour stress test

    We assemble and configure the hardware in our lab. Cables are precisely cut and terminated to length, and the entire system then undergoes 72-hour CPU/GPU/storage stress testing before delivery.

  4. 04
    Deployment without downtime & ongoing SLA oversight

    We install the finished, tested environment on site. We migrate data and services outside your team’s working hours, then cover the infrastructure with proactive monitoring and direct engineering support.

Complementary PCS ecosystem

Hardware is only the foundation. We provide the full operational layer.

High-performance servers and racks deliver no value without optimized applications, access policies and uncompromising security. We integrate the physical layer with your working environment.

01

Software & process automation

Put your compute resources to full use.

We deploy on-premises instances of design systems and databases, dedicated file-exchange bridges (Samba/API), local AI assistants and render farms. We eliminate bottlenecks and per-seat SaaS cloud license costs. We integrate these systems with your existing infrastructure and automate repetitive operational processes, so your team works in one coherent environment instead of scattered tools.

See business systems and tools →
02

Data sovereignty & network security

Isolate your infrastructure from external threats.

We configure hardened firewalls (IDS/IPS), VLAN separation for critical subnets, encrypted site-to-site tunnels and policies for immutable backups (ZFS snapshots). Your data stays under your organization’s full control — processed and stored on-premises, with an encrypted off-site backup kept solely for disaster recovery.

See our security architecture →
03

Continuous engineering oversight & SLA

Operational continuity without a full-time administrator.

We cover your infrastructure with proactive telemetry monitoring (temperature, drive wear, power rails). We provide a response time set individually in your SLA, regular disaster recovery (DR) testing and direct access to an engineer. This way, we detect failures and anomalies before they affect your team — not only once a frustrated user reports them. We act proactively instead of fighting fires.

See support models and SLAs →

Technology stack

The hardware standards and system platforms we build on.

Compute & GPU acceleration

  • AMD EPYC™
  • Intel® Xeon® Scalable
  • NVIDIA RTX™ PRO Blackwell
  • Multi-Instance GPU (MIG)
  • DGX-class nodes

Storage & file systems

  • OpenZFS
  • All-NVMe U.2 arrays
  • TrueNAS Enterprise
  • SAS/SSD tiering
  • Immutable snapshots

Virtualization & platforms

  • Proxmox VE
  • Linux KVM
  • LXC containers
  • Docker Engine
  • Live migration and HA

Networking & rack infrastructure

  • 15–18U office rack cabinets
  • Quiet, high-performance 4U servers
  • 10/25/100 GbE backbone
  • OPNsense firewalls
  • Out-of-band IPMI/BMC

Engineering matched to your scaleLet’s design an architecture for your team’s real workload.

We’ll analyze your office’s heat load, rack size, IOPS requirements and the GPU power you need for AI and rendering. We’ll prepare a complete concept without pushing unnecessary licenses.

  • Quiet office rack or server room
  • GPU sizing without subscriptions
  • Talk to an engineer

Confidential requirements review
Response within 24 hours on business days